Work · Case study · 04
OpenPrinting site search
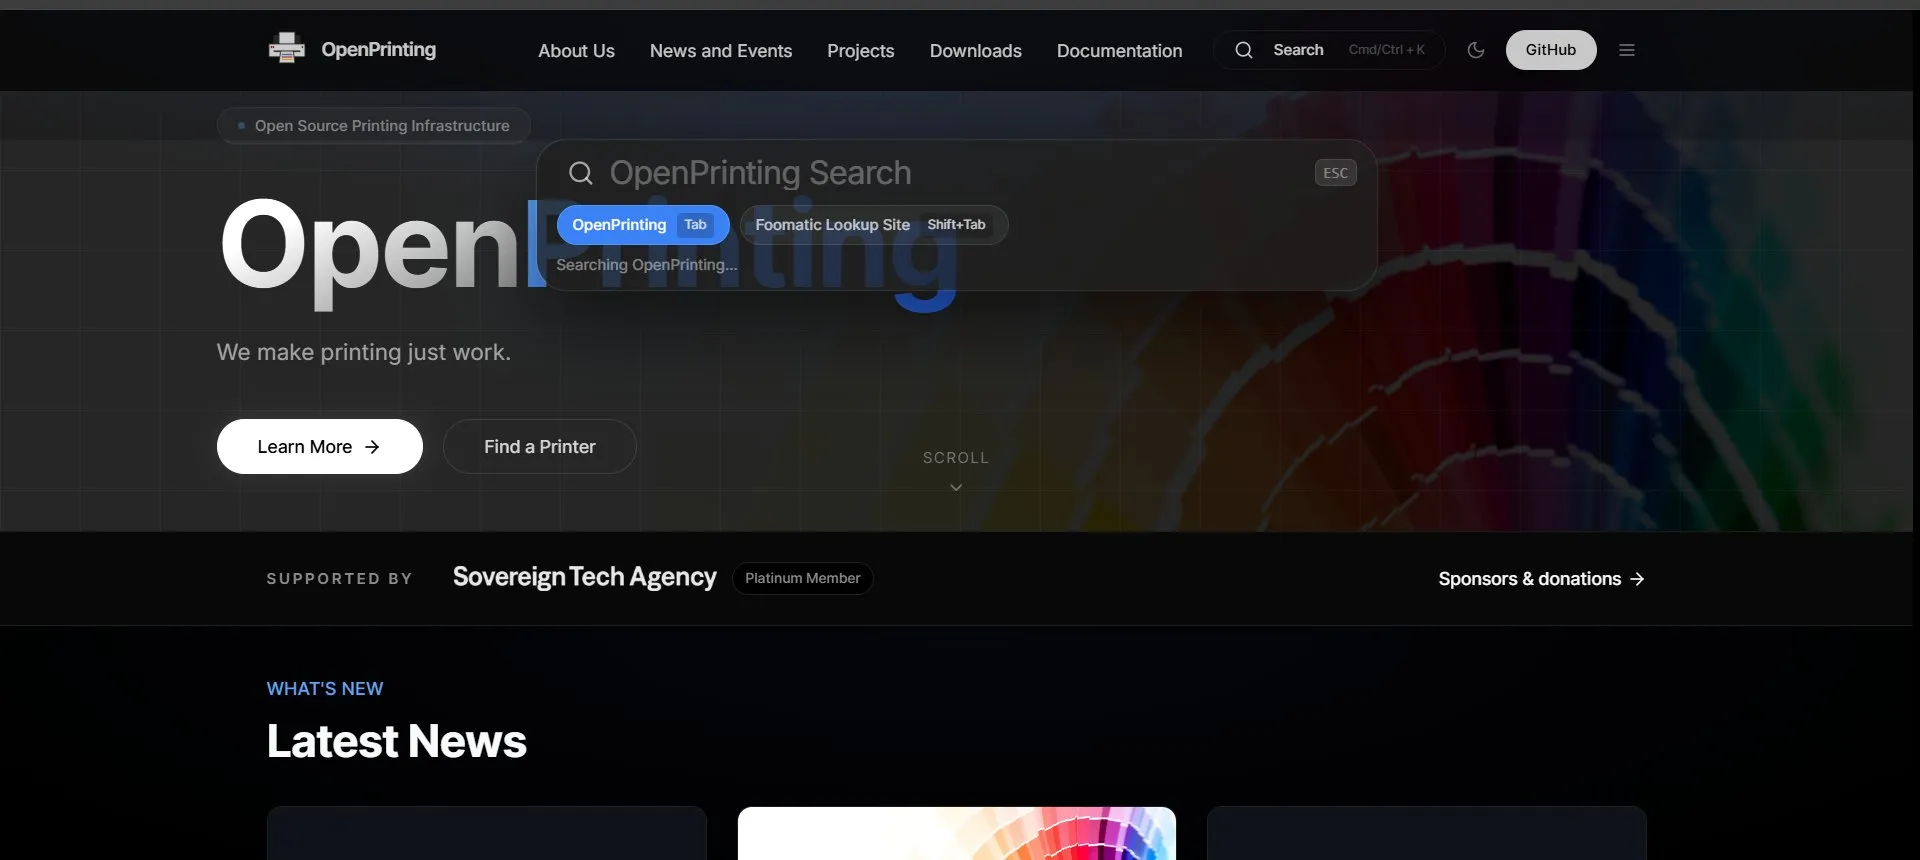
Site-wide search for a statically exported Next.js site with no backend. A build step parses every post into a JSON index; the browser loads it once and answers queries locally with weighted, fuzzy ranking. Opens with Cmd/Ctrl + K on openprinting.github.io today.
Architecture
The system, at a glance.
01 — Claims and evidence
| Claim | Measurement | Context | Verify |
|---|---|---|---|
| Live in production | openprinting.github.io | press Cmd or Ctrl + K on any page; the index is served from /search/static-index.json | live index ↗ |
| Index size | 263 documents | measured from the live index on 2026-09-29; the PR indexed 200+ posts at the time | live index ↗ |
| Search system | +793 lines · 14 files | build-time extractor, runtime engine, modal UI, architecture doc; 13 commits, merged 2026-03-06 | PR #18 ↗ |
| Deployment fix | 1 file | the generated index was gitignored and never reached GitHub Pages; fixed the same day | PR #22 ↗ |
| Merged and in production | 2 pull requests | reviewed and merged in the staging repository, then promoted to the production history under my name | production history ↗ |
| Ranking | title ×3 · headings ×2 · body ×1 | fuzzy threshold 0.2, top 8 results, 200 ms debounce | PR #18 ↗ |
02 — The problem
The OpenPrinting website is a statically exported Next.js application on GitHub Pages. There is no server to run a query against, and the site had a placeholder search that did nothing useful. It also had more than 200 news posts and pages worth finding.
The constraint was the same one that later shaped the GSoC work: anything expensive has to happen at build time, and the browser has to do only the cheap part. The result is a search that works entirely from a JSON file the site already ships.
03 — How it works
From Markdown to an answer, with no server
- A prebuild step runs before every production build and walks every Markdown post in the content directory.
- Each post is parsed into an AST with unified and remark-parse, then walked to extract the title, the h1 to h3 headings, a snippet, and normalised body text. Code blocks and formatting artifacts are stripped so they cannot pollute results.
- The extractor writes one versioned static index file, public/search/static-index.json, which the deploy ships like any other asset. The live index holds 263 documents.
- In the browser, MiniSearch builds its in-memory index lazily on the first query, so visitors who never search pay nothing.
- Ranking is weighted: title matches count three times, headings twice, body once. Fuzzy matching with a 0.2 threshold tolerates typos, and results are capped at the top eight.
- The modal opens with Cmd or Ctrl + K, debounces input by 200 ms, shows a loading state during initialisation, handles empty results, and closes on Escape.
Do the expensive work before deploy. Keep the browser’s job small.
04 — Decisions
Two layers, separated on purpose
A build-time indexing layer and a client-side runtime layer, with a typed schema between them. The build side can change how it extracts text without touching the UI, and the runtime can change ranking without re-parsing Markdown.
AST parsing instead of regular expressions
Markdown is not regular. Parsing with unified and remark-parse and walking the tree gives clean titles, headings and body text, and makes it trivial to drop code blocks, which would otherwise dominate matches with identifiers.
MiniSearch in the browser
A small, dependency-free full-text engine that supports field boosting, fuzzy matching and prefix search. It fits the static-export constraint exactly: fetch one JSON file, build the index in memory, answer locally.
Lazy initialisation and a base-path-aware fetch
The index is only fetched and built on the first keystroke, and the fetch respects the Next.js base path so the same code works in development, in preview builds and on GitHub Pages.
Designed for a second source
The schema anticipated a second index, the Foomatic driver lookup, without an architectural change. The live site now offers exactly that as a second search scope.
05 — What went wrong
Stated on purpose.
The index never reached production
The generated index file was listed in .gitignore, so the deployed site fetched a path that did not exist and search failed silently in production while working locally. PR #22 fixed the ignore rule the same day. The general lesson came back during the trailing-slash investigation months later: a build that only breaks in the deploy environment needs a check that runs in the deploy environment.
06 — Limitations
- The whole index ships to the browser on first search, about 1.9 MB uncompressed for 263 documents. Fine at this size; a much larger site would want a sharded or prefix-split index.
- Ranking is lexical. There is no semantic matching, which is the right trade for a static site with no server.
- Results are capped at eight; there is no pagination.
07 — What I’d do next
- Compress or shard the index if the post count keeps growing.
- Add a CI check that the deployed site can fetch the index, so a regression of the PR #22 bug is caught before merge.
Last verified 2026-09-29 · numbers reported as measured, with their context and source